CPU and memory are the bare minimum to keep an eye on when you run workloads on Kubernetes. Prometheus and Grafana are great for history and alerting, but they take work to set up and maintain, and they live in a different tool from the one you troubleshoot with.
Aptakube shows usage where you already are: in the lists and details of your resources, with nothing extra to set up.
Usage next to requests and limits
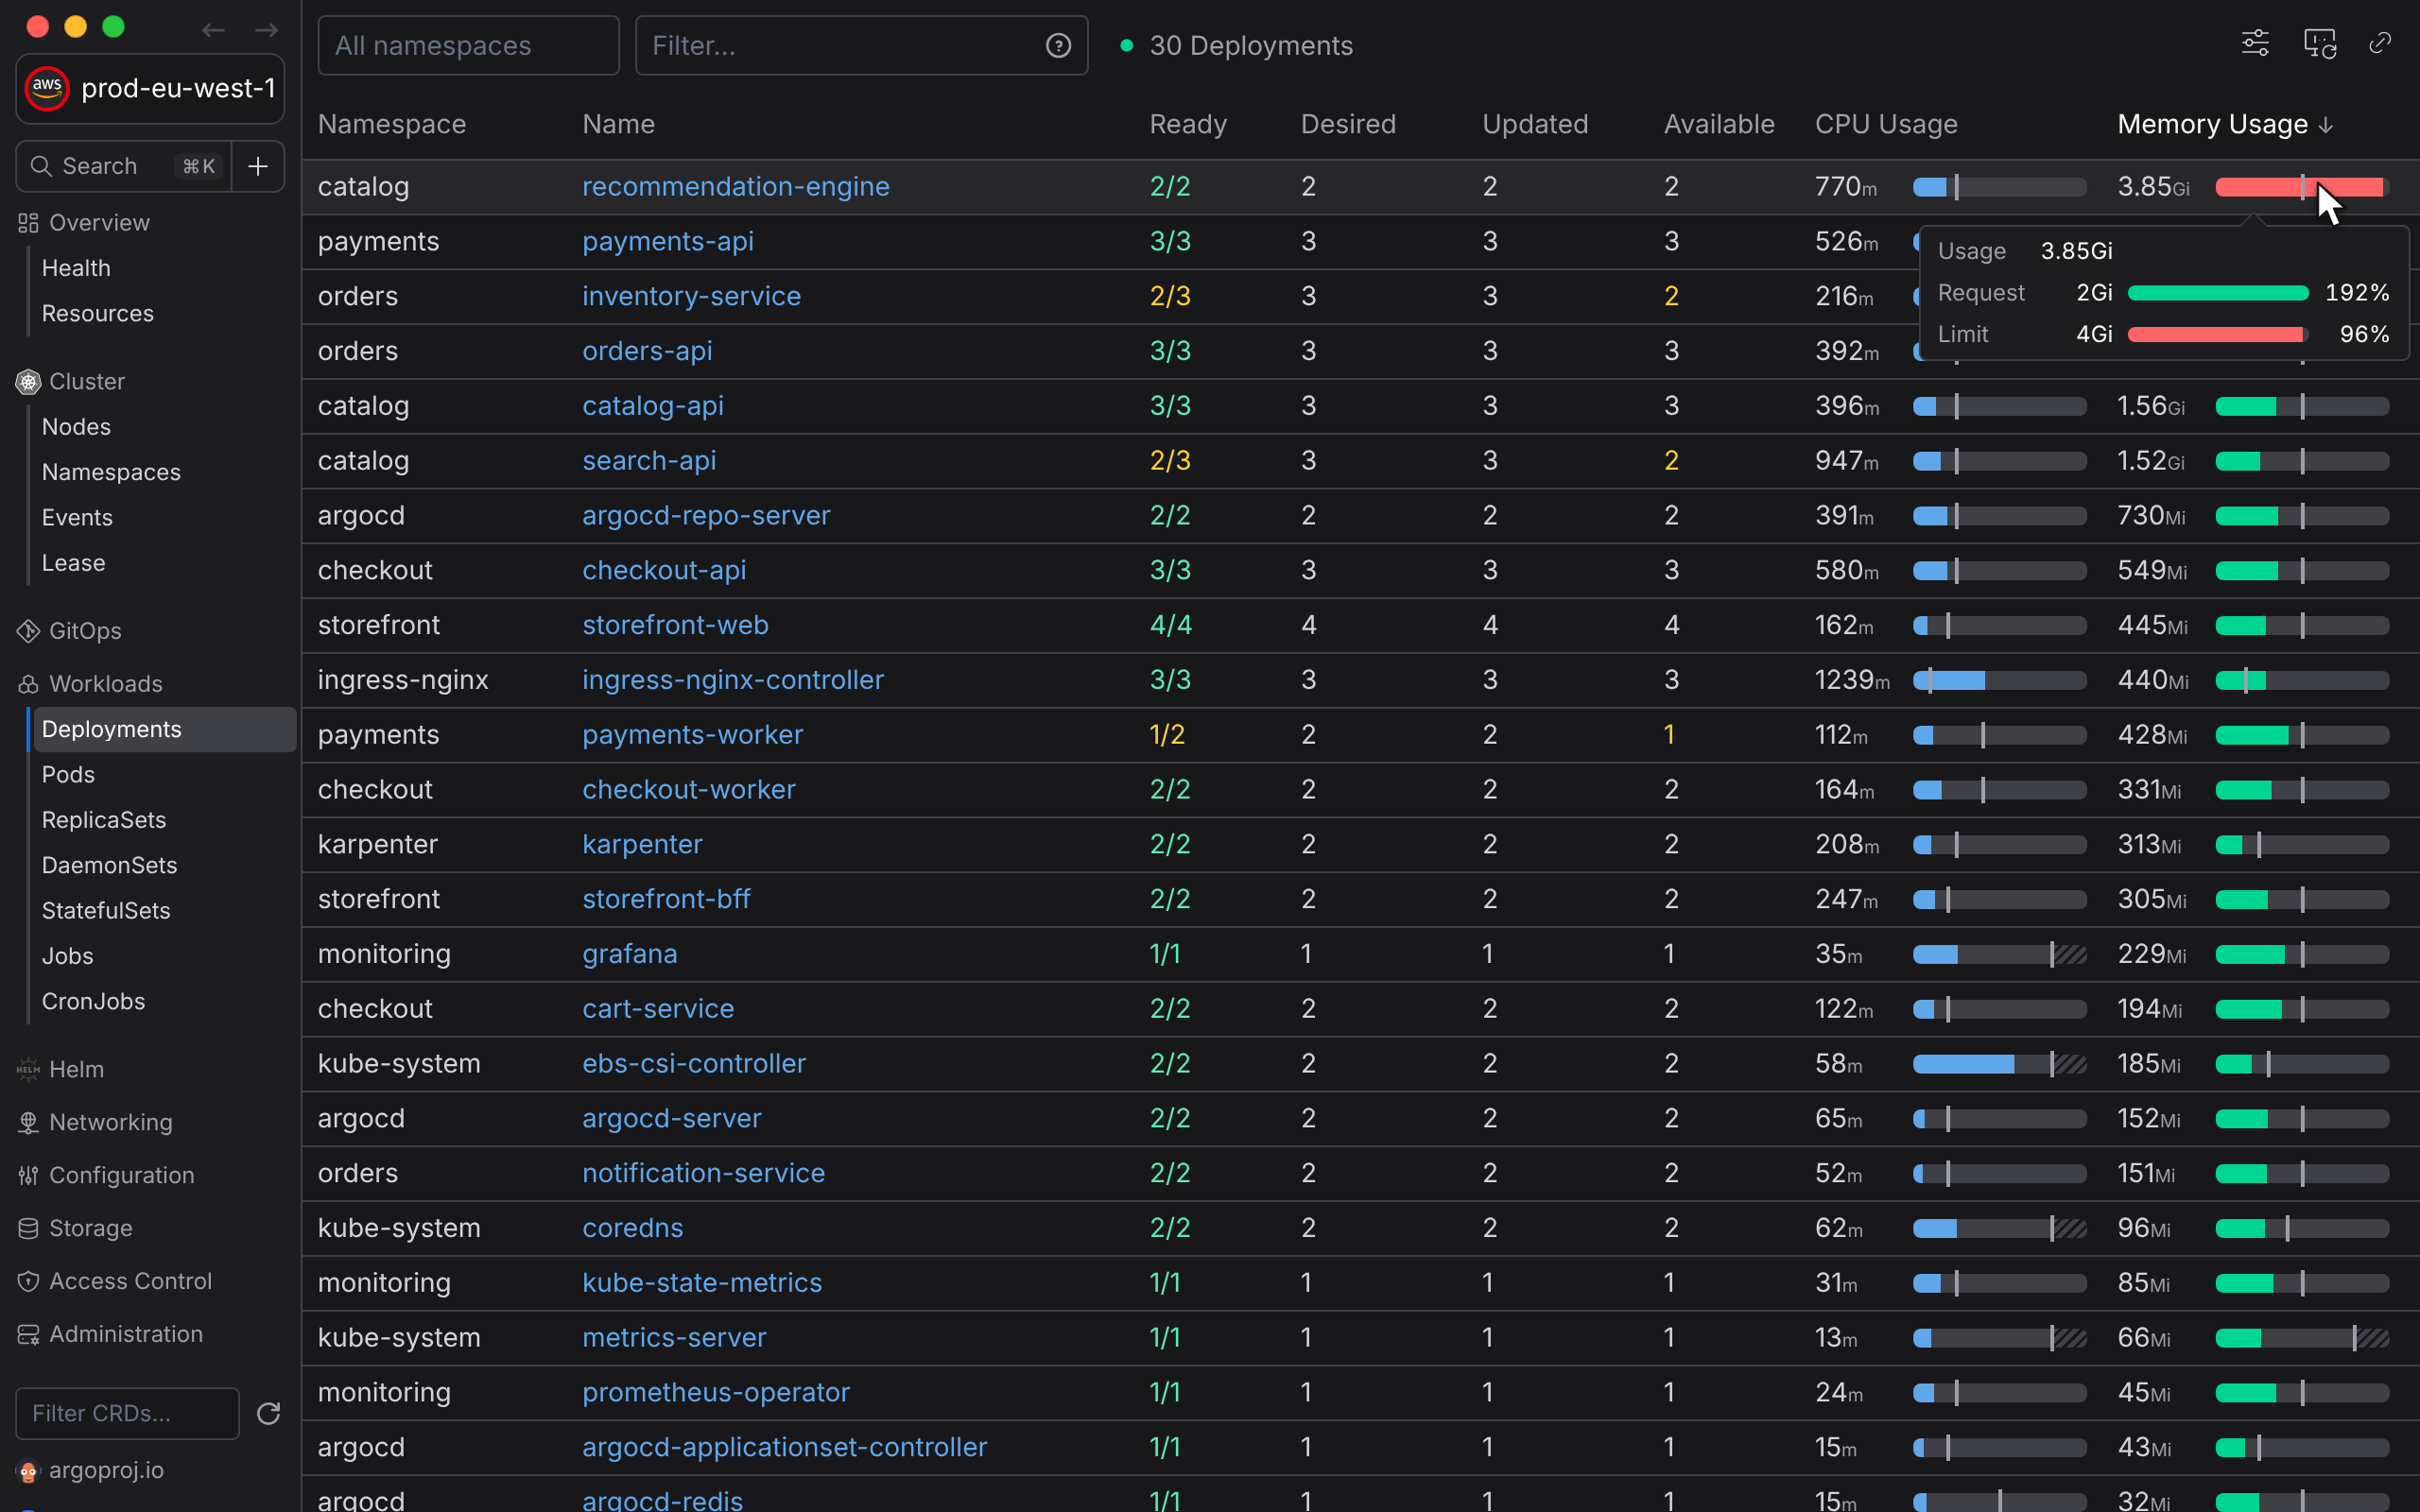
Lists of Pods, Deployments, StatefulSets, DaemonSets, ReplicaSets and Nodes have CPU and memory columns. Each bar shows the current usage, with markers for the requests and limits, so you can tell at a glance whether a workload is sized right.
Bars turn yellow when a workload uses more than it requests or gets close to its limit, and red when it's about to hit it. Hover any bar for the exact numbers.
Node capacity at a glance
Open a Node to see how its CPU and memory are used, how much is allocatable, how much its Pods requested and how high their limits go. It's an easy way to find nodes that are overcommitted, or full because of requests even though they're mostly idle.
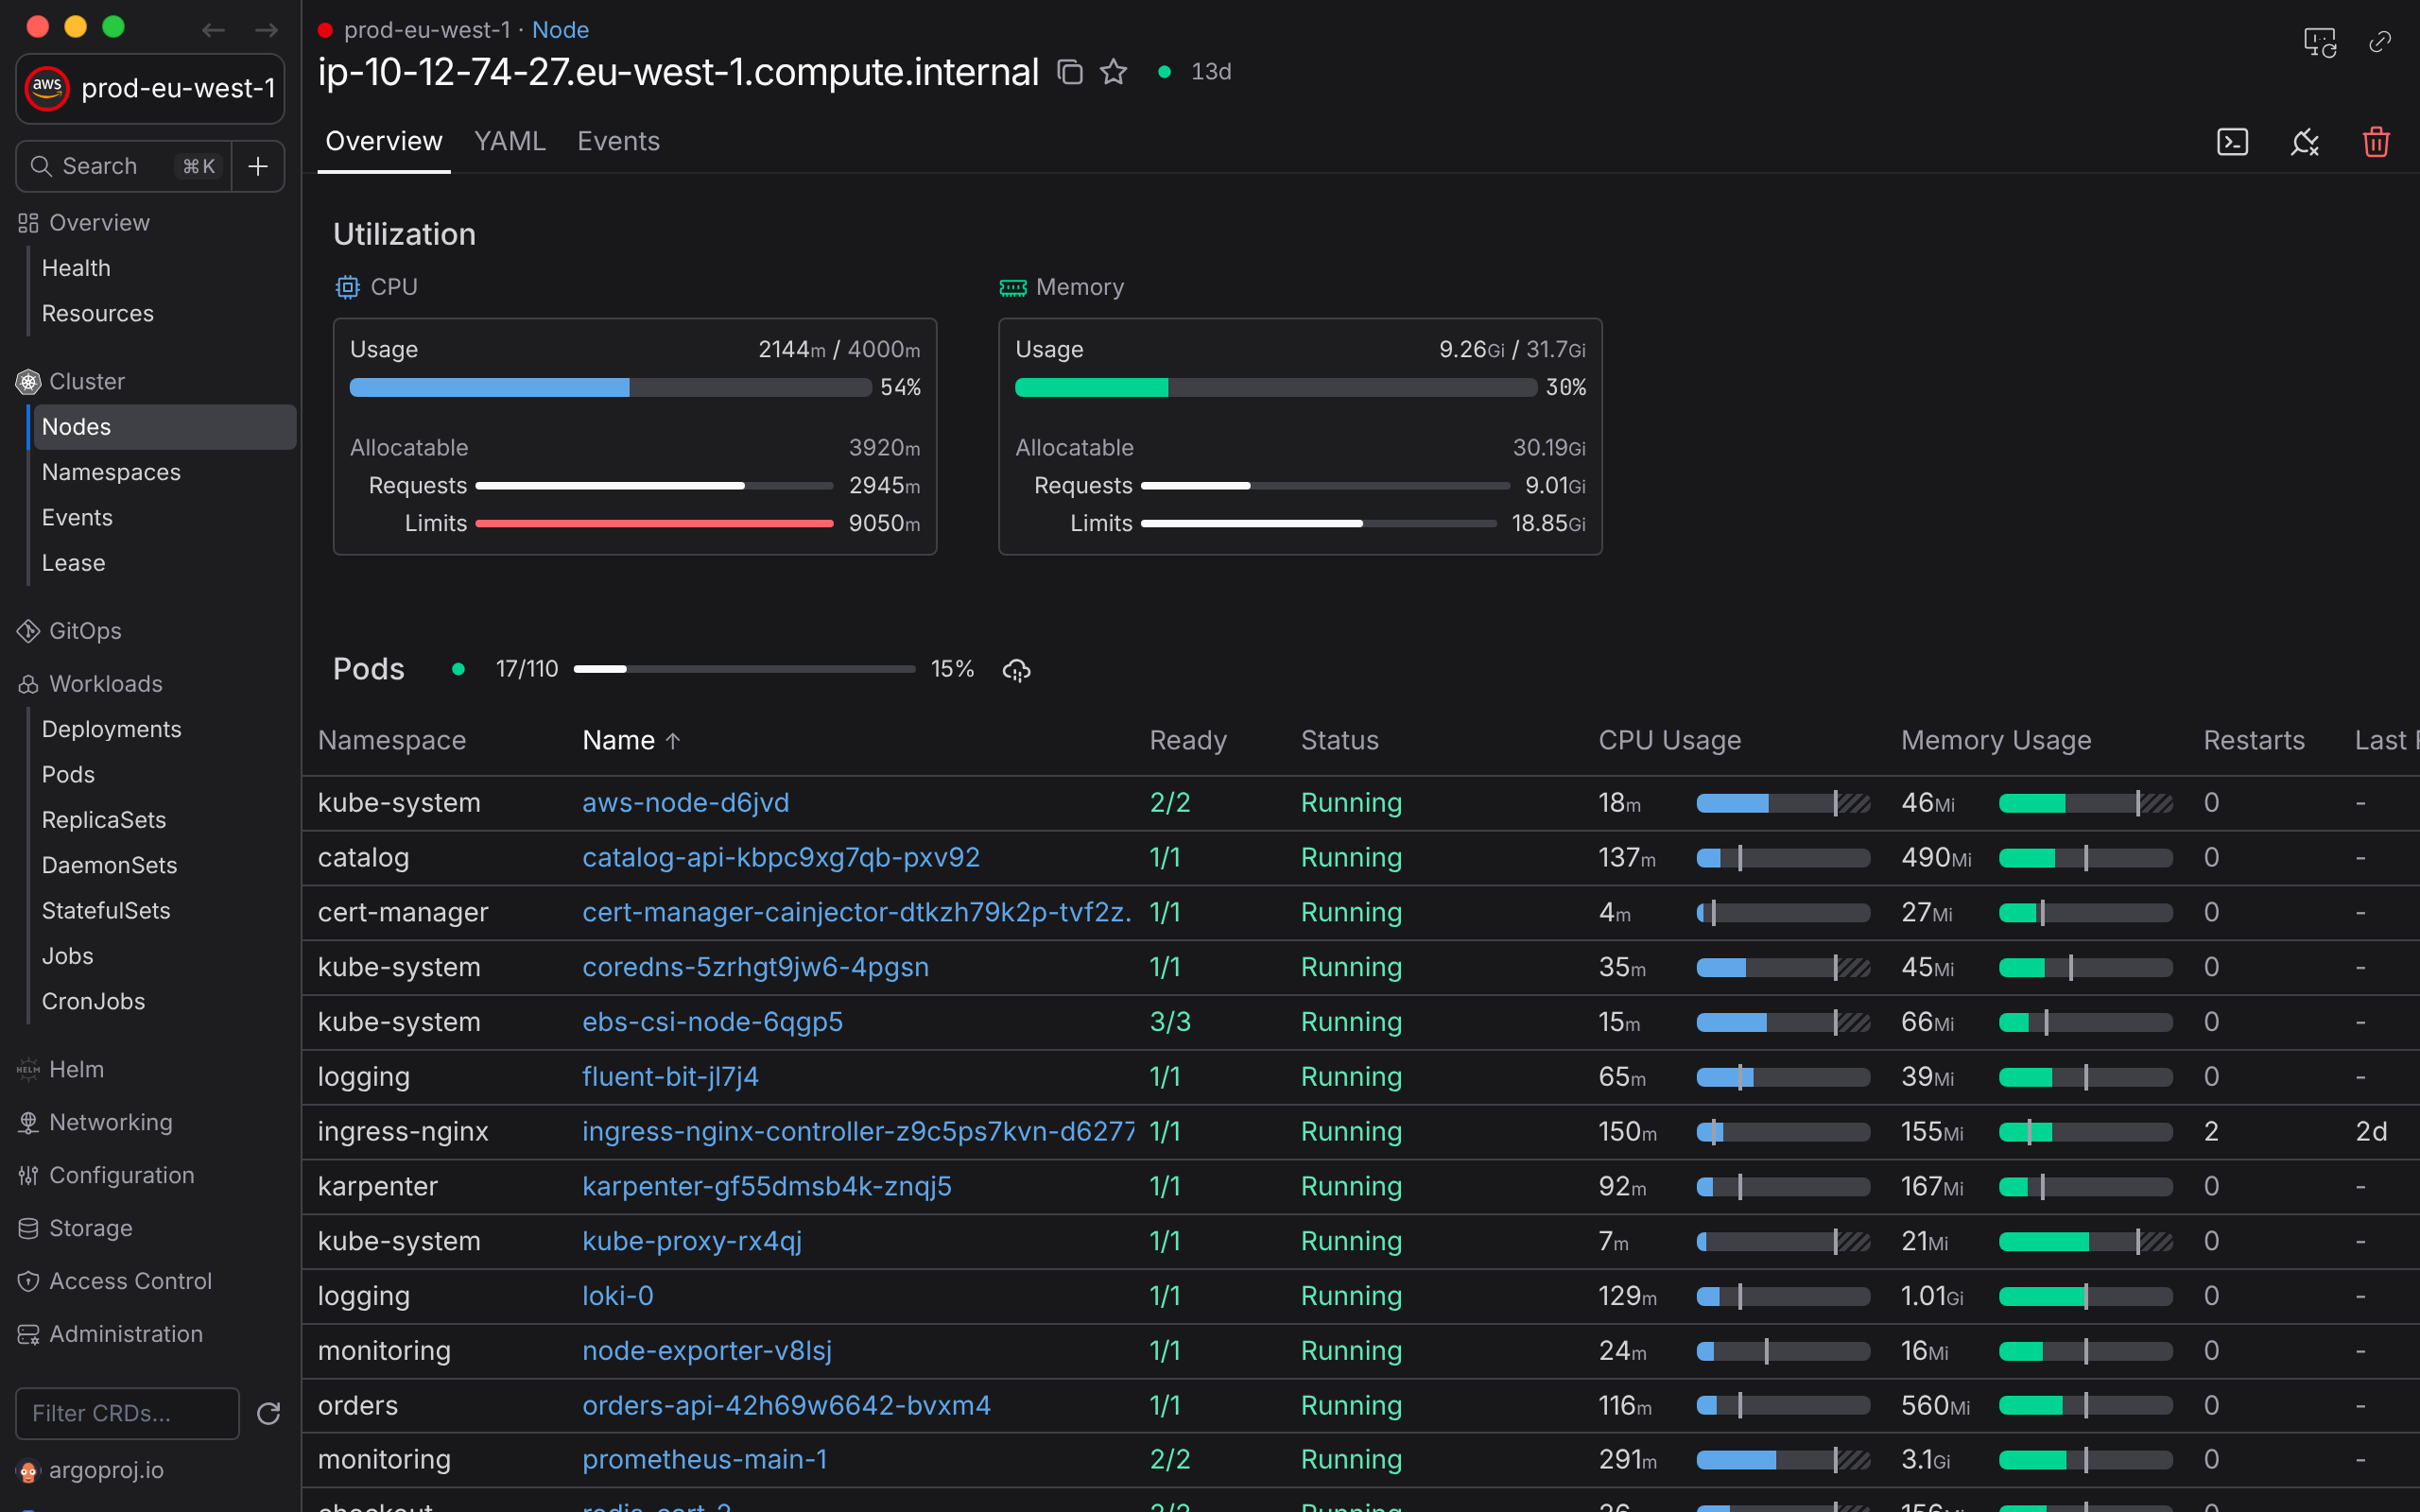
The list of Pods underneath shows what each one uses, and how many more Pods the Node can still schedule.
Every cluster's capacity, and what to resize
The Resources page has a card per cluster: how much of its nodes' CPU and memory is in use, how much its Pods requested out of what's allocatable, and how many Pods run out of how many fit. With several clusters open, the cards sit side by side.
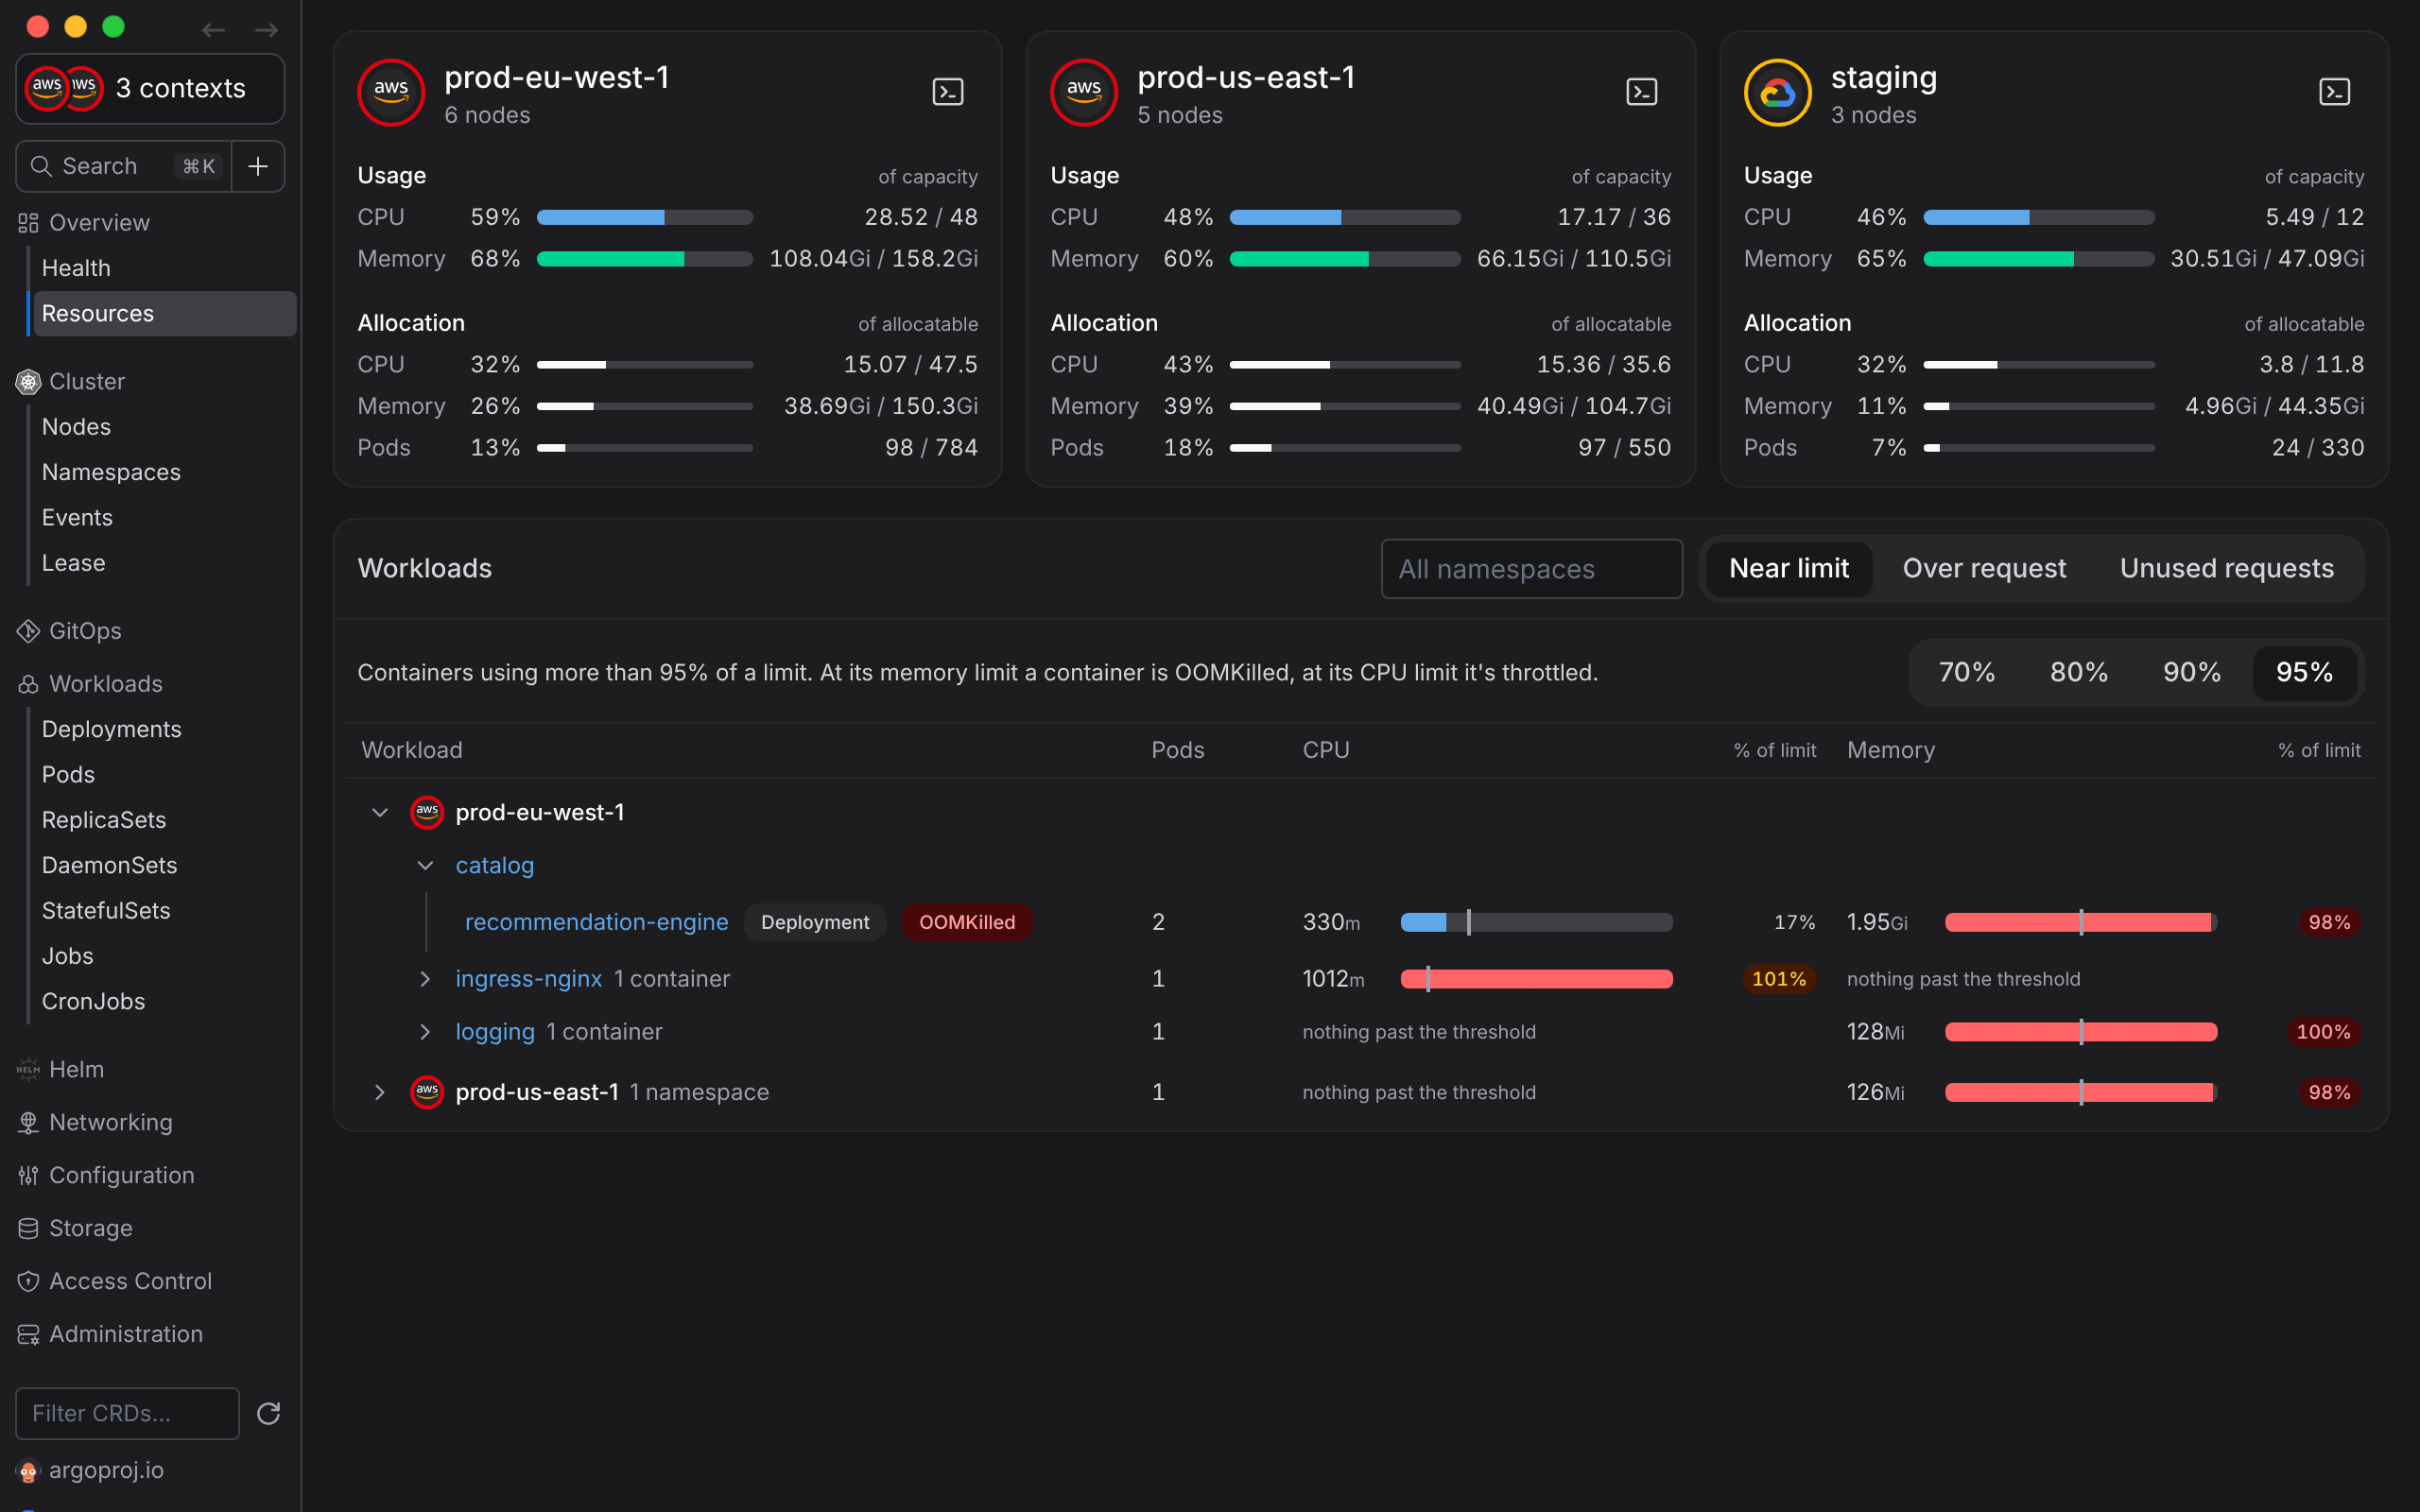
Under the cards, the workloads worth resizing, grouped by cluster and namespace:
- Near limit: containers using more than 70, 80, 90 or 95% of a limit. At its memory limit a container is
OOMKilled, at its CPU limit it's throttled. - Over request: containers using more than they request, which the scheduler didn't plan for.
- Unused requests: containers using a small part of what they request, which keeps capacity from other Pods.
Built on the Kubernetes Metrics API
Aptakube reads metrics from the standard Kubernetes Metrics API, the same one used by kubectl top. That makes it compatible with metrics-server, which many managed clusters already run, and is easy to install on the ones that don't.
Already running Prometheus? Install the prometheus-adapter, which serves the Metrics API from your Prometheus data, and Aptakube works with it too.